Step Distillation
On this page
Step distillation is an important optimization technique in LightX2V. By training distilled models, it significantly reduces inference steps from the original 40-50 steps to 4 steps, dramatically improving inference speed while maintaining video quality. LightX2V implements step distillation along with CFG distillation to further enhance inference speed.
🔍 Technical Principle
DMD Distillation
The core technology of step distillation is DMD Distillation. The DMD distillation framework is shown in the following diagram:
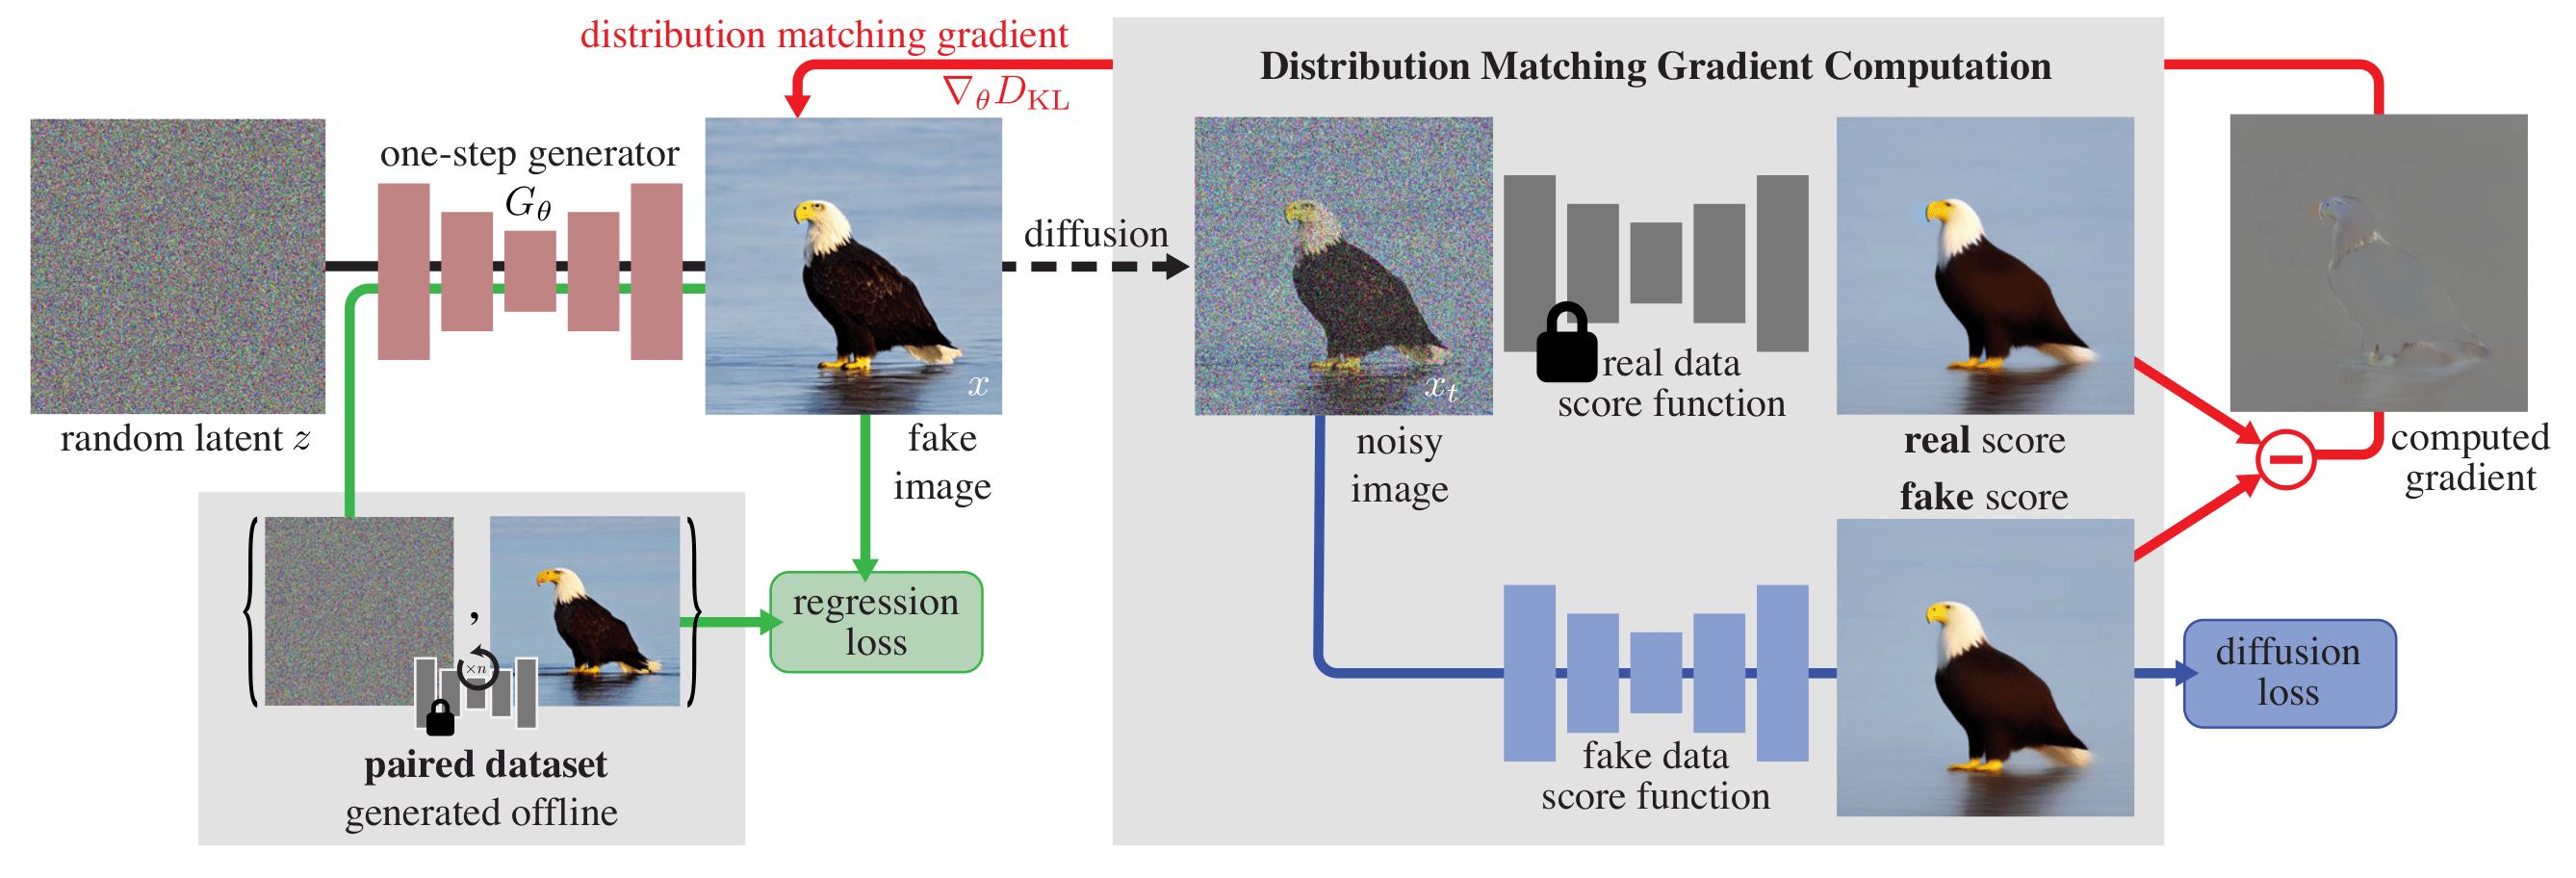
The core idea of DMD distillation is to minimize the KL divergence between the output distributions of the distilled model and the original model:
Since directly computing the probability density is nearly impossible, DMD distillation instead computes the gradient of this KL divergence:
where \(s_\text{real}(x) =\nabla_{x} \text{log}~p_\text{real}(x)\) and \(s_\text{fake}(x) =\nabla_{x} \text{log}~p_\text{fake}(x)\) are score functions. Score functions can be computed by the model. Therefore, DMD distillation maintains three models in total:
real_score, computes the score of the real distribution; since the real distribution is fixed, DMD distillation uses the original model with fixed weights as its score function;fake_score, computes the score of the fake distribution; since the fake distribution is constantly updated, DMD distillation initializes it with the original model and fine-tunes it to learn the output distribution of the generator;generator, the student model, guided by computing the gradient of the KL divergence betweenreal_scoreandfake_score.
References:
Self-Forcing
DMD distillation technology is designed for image generation. The step distillation in LightX2V is implemented based on Self-Forcing technology. The overall implementation of Self-Forcing is similar to DMD, but following DMD2, it removes the regression loss and uses ODE initialization instead. Additionally, Self-Forcing adds an important optimization for video generation tasks:
Current DMD distillation-based methods struggle to generate videos in one step. Self-Forcing selects one timestep for optimization each time, with the generator computing gradients only at this step. This approach significantly improves Self-Forcing's training speed and enhances the denoising quality at intermediate timesteps, also improving its effectiveness.
References:
LightX2V
Self-Forcing performs step distillation and CFG distillation on 1.3B autoregressive models. LightX2V extends it with a series of enhancements:
- Larger Models: Supports step distillation training for 14B models;
- More Model Types: Supports standard bidirectional models and I2V model step distillation training;
- Better Results: LightX2V uses high-quality prompts from approximately 50,000 data entries for training;
For detailed implementation, refer to Self-Forcing-Plus.
🎯 Technical Features
- Inference Acceleration: Reduces inference steps from 40-50 to 4 steps without CFG, achieving approximately 20-24x speedup
- Quality Preservation: Maintains original video generation quality through distillation techniques
- Strong Compatibility: Supports both T2V and I2V tasks
- Flexible Usage: Supports loading complete step distillation models or loading step distillation LoRA on top of native models; compatible with int8/fp8 model quantization
🛠️ Configuration Files
Basic Configuration Files
Multiple configuration options are provided in the configs/distill/ directory:
| Configuration File | Purpose | Model Address |
|---|---|---|
| wan_t2v_distill_model_4step_cfg.json | Load T2V 4-step distillation complete model | hugging-face |
| wan_i2v_distill_model_4step_cfg.json | Load I2V 4-step distillation complete model | hugging-face |
| wan_t2v_distill_lora_4step_cfg.json | Load Wan-T2V model and step distillation LoRA | hugging-face |
| wan_i2v_distill_lora_4step_cfg.json | Load Wan-I2V model and step distillation LoRA | hugging-face |
Key Configuration Parameters
- Set
distill_methodto"dmd2"to use WanStepDistillScheduler. infer_steps,denoising_step_listandsample_shiftare set to parameters matching those during training, and are generally not recommended for user modification.- Keep
enable_cfgconsistent with the selected model configuration. The Wan2.1 examples here usefalse. - When using a distilled LoRA, set its path and strength in
lora_configswhile keepingdistill_method: "dmd2". Omitlora_configswhen loading a complete distilled model without an additional LoRA.
The following is a fragment to merge into the complete config for the selected weights. infer_steps is the inference step count, denoising_step_list lists the denoising timesteps, and sample_shift is the scheduler's timestep shift.
{
    "distill_method": "dmd2",
    "infer_steps": 4,
    "denoising_step_list": [
        1000,
        750,
        500,
        250
    ],
    "sample_shift": 5,
    "enable_cfg": false,
    "lora_configs": [
        {
            "path": "path/to/distill_lora.safetensors",
            "strength": 1.0
        }
    ]
}
📜 Usage
Model Preparation
Complete Model:
Set --model_path to the original Wan model directory containing config.json and encoder/VAE weights. Set dit_original_ckpt to the distilled safetensors file, or use dit_quantized_ckpt with dit_quantized=true and the matching dit_quant_scheme for quantized weights. If using distill_model.pt, remove dit_original_ckpt from the config and place the file directly under --model_path.
LoRA:
- Place the downloaded LoRA in any location
- Modify the
lora_configs[].pathparameter in the configuration file to the LoRA storage path
Inference Scripts
T2V Complete Model:
I2V Complete Model:
Step Distillation LoRA Inference Scripts
T2V LoRA:
I2V LoRA:
🔧 Service Deployment
Start Distillation Model Service
Modify the startup command in scripts/server/start_server.sh:
python -m lightx2v.server \
  --model_cls wan2.1 \
  --task t2v \
  --model_path $model_path \
  --config_json ${lightx2v_path}/configs/distill/wan21/wan_t2v_distill_model_4step_cfg.json \
  --port 8000
Run the service startup script:
For more details, see Service Deployment.
Usage in Gradio Interface
See the separate Gradio-Lightx2v repository for installation and usage instructions.